Developer tools · HTML WYSIWYG editor
The DOM Explained for Editors: Why HTML Is a Tree, Not a Text File
· Background
html dom contenteditable
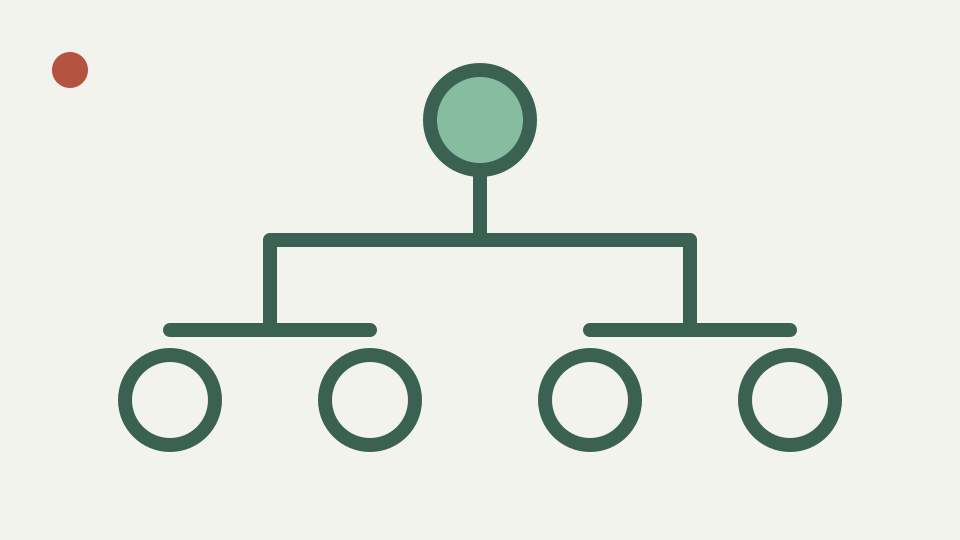
Introduces the Document Object Model for non-programmers, covering nesting rules, parent and child elements, and how browsers repair invalid nesting, to explain editor behaviour that otherwise seems arbitrary.
Why your <p> closed itself — opens with markup that changed after a paste
A paragraph can appear to close or move after a fragment passes through an editor because the resulting tree—not the author’s original character sequence—is what ultimately matters. ToolAcre adds another transformation: it tokenizes and rewrites the browser-derived source under its own allowlist.
When source changes, ask which stage changed it. The browser may have mutated the contenteditable DOM, or the sanitizer may have mapped an alias, unwrapped a node or balanced accepted tags. Calling every difference “the browser fixed it” hides this important boundary.
Boxes inside boxes — introduces the tree model with a short example
Think of elements as boxes connected by parent-child relationships. In `<p>Read <strong>carefully</strong>.</p>`, p is the parent of text, strong and more text; strong is the parent of the word carefully. Source indentation can illustrate the tree but does not create the relationship.
ToolAcre’s pretty formatter puts block containers on lines and keeps inline elements with surrounding text. Lists receive indented li lines. This format is for reading sanitized output. The actual model remains nested elements and text nodes, regardless of whether source is compact or spread across lines.
Allowed nesting is balanced by ToolAcre’s rewriter; browser content models are broader
HTML defines content models that are much broader and more detailed than this editor’s policy. ToolAcre permits a specific set but does not validate every semantic nesting rule. Its stack ensures well-formed closure among allowed tags; that is not proof that every resulting relationship is ideal HTML for a destination.
For example, a list should contain appropriate list items, yet the generic stack can preserve unusual allowed combinations because it is not a schema validator. Authors should construct sensible headings, paragraphs and lists through the toolbar or reviewed source, then validate under destination requirements when correctness is consequential.
ToolAcre repairs accepted tags with a stack, not the complete HTML parsing algorithm
Browsers apply a full HTML parsing algorithm with error recovery. ToolAcre does not reimplement it. Its tokenizer recognizes the structures needed by the allowlist, and its writer closes accepted inner elements when a crossing end tag appears. It drops stray closes and closes remaining opens at the end.
The source explicitly names parser differentials as a reason not to treat the module as a general hostile-input XSS filter. A browser can interpret deliberately malformed strings differently. The preview sandbox provides an independent limit on execution inside ToolAcre, while servers still need proper HTML5-aware sanitation.
Text nodes and whitespace — covers why spaces and line breaks between tags exist in the tree
Text between elements becomes text tokens, including whitespace characters. The pretty formatter collapses ordinary whitespace outside pre, while pre content is retained exactly. Plain-text conversion inserts newlines after block endings and for br, then reduces runs of excessive blank lines.
Whitespace therefore participates differently at each stage. Visual spacing can come from text, br, block boundaries or CSS. Inspect nodes and characters rather than treating every visible gap as a margin. The sanitizer may normalize formatting whitespace without changing the words a reader sees.
Worked example: tracing a two-paragraph note with a list — reads the produced markup as a tree, identifying parents and children
Build `<h2>Checklist</h2><p>Read <strong>carefully</strong>.</p><ul><li>Source</li><li>Preview</li></ul>`. The fragment has three root-level element children. The paragraph contains text and strong; the list contains two li children, each with text.
Switch from source to visual and back. The allowed tree should remain balanced, and pretty mode will place the heading and paragraph on lines while indenting list items. This exercise is controlled; it does not demonstrate every malformed input or browser repair path.
What this does not cover — JavaScript DOM programming or the CSS box model
This article does not teach JavaScript DOM programming, mutation observers, Selection APIs or the CSS box model. Element tree and layout box tree are related but not identical. It also does not claim the hand-written token list is a browser DOM.
No generalized security conclusion follows from a tidy tree. An attacker can target parsing differences and URLs, which is why output filtering, sandboxed preview and server sanitation remain distinct. Use the tree model to reason about structure, not to waive the receiving system’s security review.
Takeaway: think in trees — summarises the mental model and how the markup output of ToolAcre's HTML WYSIWYG editor shows the tree you are building
Think in trees when visual behavior seems arbitrary. Identify the parent, children and text nodes you intended, then compare them with filtered source. ToolAcre makes this inspection practical by pairing contenteditable drafting with a readable rewritten fragment.
A strong mental model also reveals limits: unwrapped div loses a parent, dropped script loses its subtree, and b becomes strong. Once those transformations are explicit, corrections become structural decisions rather than repeated visual nudges whose markup remains unknown.